The most common way I've seen sensor data get corrupted is one line long, and it doesn't look like corruption. It looks like resample().mean(). Or a forward-fill. Or a pivot table quietly filling its blanks. Run any of them over a series with an outage in it, and your dataset now contains readings from hours when the instrument was off.
I want to make the case that this is a bigger deal than it's treated as, that a gap is not a blank to be repaired but a measurement in its own right, and that "what does your tooling do with gaps" is one of the most revealing questions you can ask of any data stack, including ours.
Nobody splices security footage
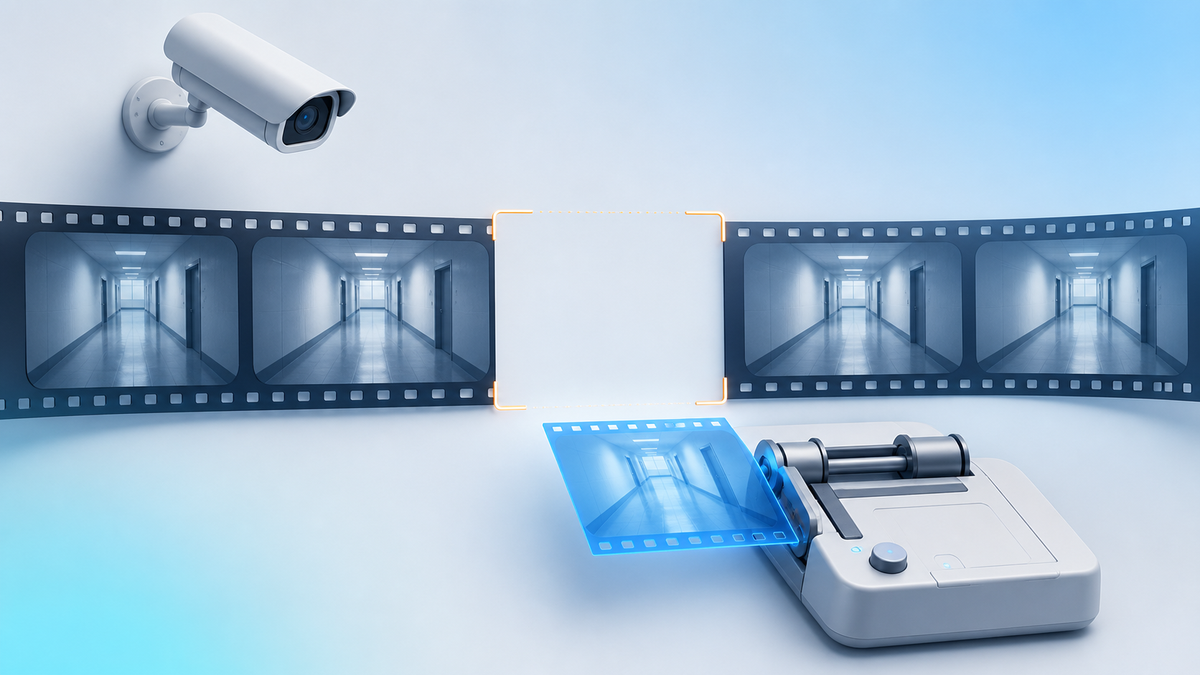
Here's the analogy I keep coming back to. If a security camera was off from 2 a.m. to 8 a.m., nobody proposes splicing in six hours of plausible-looking footage of an empty hallway. The missing hours are the finding. Anyone reviewing the tape needs to know, first and loudest, that there is no tape, because "we can't see what happened" and "nothing happened" are entirely different statements, and the difference is the whole reason the camera exists.
A forward-fill is spliced footage. An interpolated gap is an empty hallway rendered from the frames on either side. The values look right, the chart looks continuous, and the one thing the record can no longer tell you is the thing that mattered: the instrument wasn't there.
What a gap actually says
In environmental monitoring, the gap is frequently the most diagnostic feature in the series. A dead battery says something about your site maintenance. A fouled probe says something about the water. A comms outage that coincides with the storm event you deployed the network to catch - that's not missing data, that's the finding of the season, and it's exactly when the fabricated values do the most damage, because the interesting periods are the ones people zoom in on.
And the failure compounds quietly downstream. An averaging window that includes fabricated values reports the wrong mean with full confidence. An exceedance count over a filled series can miss the event entirely, or invent one. In my experience the error rarely announces itself; it surfaces months later as a number in a report that someone, eventually, asks you to defend.
Not all gaps are the same gap
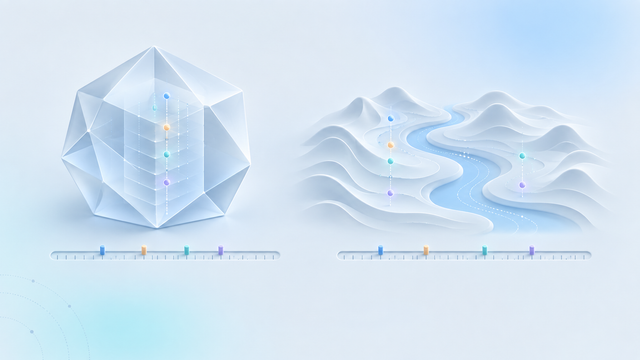
One more distinction before the tooling, because it's the one that turns gap-preservation from hygiene into analysis. "Missing" is not one thing. A sensor that was offline is an outage, the value is unknown. A reading below the instrument's detection limit is not unknown at all; it's a bounded fact ("less than X"), and treating it as a gap throws information away just as surely as filling a real gap invents it. Data that hasn't arrived yet from a delayed logger is a third thing, absent now, present next week. And a decommissioned site is a fourth: absent forever, on purpose, with a date.
Collapse those four into one undifferentiated blank and every downstream consumer, your regulator, your client, your AI, has to guess which one they're looking at. They will guess wrong at the worst moment. The discipline that fixes it is the same one that fixes filling: make the distinction explicit in the record, at the moment you know it, instead of trusting everyone downstream to reconstruct it.
The defaults are against you
None of this is a bug in your tools. The pandas documentation is perfectly upfront about what its fill methods do, forward fill works "by propagating the last valid observation forward," exactly as designed; they were built for cross-domain work, finance mostly, where a value genuinely persists between observations. The price of a stock between trades is the last trade. The concentration of benzene between working samples is not the last sample. The tool is fine. The default, imported into our domain, splices the tape, same empty hallway, rendered a column at a time.
And it's not just the scripting layer. The same assumption is built into far more sophisticated machinery. Snowflake's ML-functions preprocessing documentation describes what happens when a series fed to its anomaly detection has missing time steps: the model fills them automatically, zero if your value aggregates as a sum, linear interpolation otherwise, as built-in preprocessing before training. There's no way to tell it "this interval isn't a reading, it's an outage." The gap gets a plausible value slid over it by the very tool that's supposed to notice something's wrong. That's not carelessness on their part; it's a reasonable default for the generic time-series their customers mostly have. It's simply the wrong physics for a sensor that can be offline.
Preserve by default, interpolate by decision
The fix is a principle, and it has to live in the data model rather than in analyst discipline, because discipline doesn't survive staff turnover and deadline pressure. The principle: gaps are preserved by default; filling them is an explicit, recorded, per-series decision.
Here's what that looks like structurally in Datasparks, as one existence proof that it can be done. Every metric keeps an observed series, the data as it arrived, untouched by any resampling, permanently. When you create a harmonized view for cross-instrument comparison, that view carries an explicit gap tolerance as part of its identity: short gaps inside your stated tolerance can be bridged by the method you chose; anything longer stays empty. Not hidden, empty, on purpose, visibly. If you want interpolation, you can have it: you say so, per series, with the method and threshold recorded, and the observed series remains underneath as the ground truth you can always return to.
I want to be fair to interpolation, because the sin here is silence, not filling. There are legitimate reasons to fill a gap, a regular process, a short dropout, a method you can state and defend. Plenty of careful teams do it well. The difference between careful and corrupt isn't whether you interpolated; it's whether the record shows that you did, where, and how, and whether anyone downstream can un-decide it. A documented, reversible fill is a modeling choice. A silent, default one is a fabrication with good intentions.
The question to ask everything
This principle generalizes into the single most efficient test I know for a data stack, and I'd apply it to us as readily as to anything else: take a series with a six-hour outage, run it through the standard workflow, and look at what comes out. If the six hours came back filled, by a script default, a pivot, or a helpful ML preprocessor, you've learned what that stack will quietly do to the moments that matter most. It's the second dimension of our evaluation rubric for exactly that reason, and it's the gap-shaped hole in most AI analytics too; which is its own post.
Nobody splices security footage; don't let a resampler splice your sensor feed. Trust the absence. It's the one part of your data nobody can fake unless your tools do it for them.