Someone recently asked one of our shareholders a very important question. Our shareholder had been explaining what Datasparks is and what we do. The person they were talking to said "Doesn't AI do that?" Simple question, and also super insightful as to where we are in the AI-hype cycle. The answer of course is: "Datasparks is how AI does that."
I've also been following recent moves by Cloudflare and Stripe concerning "agentic wallets". Defined procedures for how an AI agent can be given a budget to buy software or data to accomplish their operator's tasks. This is an incredible concept. It seems a bit terrifying, until you actually run the economics around token use and costs, local compute constraints, and the economies of scale found in focused software solutions.
Somewhere in the next few years, a piece of software with a budget is going to face a build-vs-buy decision. I have been making those decisions my whole career, and like most engineers-turned-executives I got them wrong in a predictable direction: I built too much, because building initially seemed less expensive and the effort of sifting out the software solution that would actually solve my problem stole too much of my time. The machines are about to inherit this decision from us.
A scientist, a folder, and seventy-five million numbers
Picture a scientist at the end of a measurement campaign. Eight monitoring sites, a dozen parameters at each, minute-by-minute readings for a year and a half. Run the arithmetic and it comes to roughly seventy-five million individual measurements, sitting in a Google Drive folder as a few hundred CSV files from three different instrument vendors. One vendor changed its export format mid-campaign after a firmware update. Two sites have gaps where batteries died in a cold snap. The data was collected to answer real questions, maybe to inform a policy discussion, which means someone skeptical will eventually read the conclusions and go looking for reasons to dismiss them.
For my entire working life, this person had two options: become a data engineer for a season, or find money and patience to buy their way out. Today they have a third option, and it is the one nearly everyone now reaches for first: ask an AI agent. With AI, this stops being a story about one scientist, because the agent immediately inherits the same old decision, build or buy, and right now it can only answer one way.
The era of default-build
The last few years collapsed the marginal cost of writing software to something close to zero. Ask an assistant for parsing scripts to handle three vendors' CSV quirks and you will have working code in minutes. Ask for a gap-handling strategy, consistent normalization rules, a dashboard, a statistical summary, a chart, and it keeps going tirelessly for the price of the tokens, the little chunks of text a model is billed by. This is a genuine marvel and I refuse to be cynical about it.
But notice what it did to the old decision. Build-vs-buy used to be a deliberation; now, build is currently a reflex. The agent builds because building is the only solution it has. I think of today's AI as a brilliant, tireless intern with no experience and no purchasing power. Right now, AI cannot open an account, cannot subscribe to a service, cannot spend a dollar and nothing tells it to explore the economic efficiency of building a solution given the model, harness, and local compute constraints. Hand any problem to a person who can make things but cannot buy things, and every solution comes back as a thing they made. We have, without much reflection, wired the most capable builder in history into our work and given it exactly one answer to the oldest question in engineering economics.
Three ways a machine can get a job done
Now, put the agent in the protagonist's seat, because that is where it now sits, and walk the options the way it would. A machine facing seventy-five million readings has exactly three ways to get the job done, and the economics of the three could not be more different.
Option one: do it itself, in its head. This is what "just have the AI analyze my data" pictures, and it is worth actually pricing. Those readings, laid out as CSV rows, come to a few hundred million tokens; the assumptions are ordinary ones, about six million rows at a few dozen tokens each. At published per-token API prices, a single complete read of the corpus runs from tens of dollars with a small model to a few thousand with a flagship one, and cleansing, exploring, and analyzing are never a single pass. Worse, a context window, the amount of text a model can actually hold in view at once, tops out around a million tokens for the models most assistants run on. That is well under one percent of this corpus, so the model works in hundreds of blind chunks, each one ignorant of all the others, which is a strange posture from which to detect a season-long trend or cross-metric correlation. A language model reasoning token-by-token is simply the wrong instrument for computing a percentile across six million rows. Inference is a miracle for judgment and the most expensive method ever devised for moving bytes. Any agent that can do arithmetic will refuse this option for the bulk work, and it will be the right decision.
Option two: build a tool. This is what actually happens today, and it is the reflex I described above. The scripts are nearly free to produce. But the build arrives with three invoices that never appear in the demo. The bill for running it: the scripts execute somewhere, the data lives somewhere, the charts are served from somewhere, and all of it is metered by someone. The bill for keeping it truthful: the next firmware update, the sensor that gets swapped next March and introduces a step-change the trend analysis will happily misread, the unit conversion that was right for eleven of the twelve parameters. An asset that requires ongoing labor to stay correct is also a liability, and a data pipeline is the purest example I know.
In our experience, home-built data systems rarely die at the build, they die at month seven, when whoever understood them has moved on. And the bill for proof, the one I have come to believe decides everything: if those numbers inform a policy discussion, someone will ask which readings were flagged and why, what happened to the gaps from the dead batteries, and a summary of the quality checks and cleansing procedures that ran the data. The default settings of common analysis tooling quietly fabricate answers to that question, sliding plausible values over missing intervals unless someone deliberately intervenes. A gap is data; it says "we did not know, and here is when we didn't." A quality rule says "we dismissed this hour of data because the new sensor was acclimating to the voltage".
When the skeptical reader finds one invented interval, they do not discard the interval, they discard the campaign. An archived chat transcript of the session where an assistant wrote your pipeline is not an audit trail, and I suspect some public dispute will teach everyone that lesson at least once in the next few years.
Option three: buy the tool. Purpose-built, metered data infrastructure prices this exact job in pocket change: a campaign this size is a few gigabytes of storage and some hours of compute, which at our own published rates works out to single-digit to low-double-digit dollars a month, and the provenance, meaning the record of where every number came from and which rules checked it, comes with the service rather than being reconstructed after the fact. On pure work-task economics, for work that has to stay alive and stay defensible, this option wins and it is not close. Yet it is the one option the modern assistant cannot take, because between the agent and this door sits a checkout form asking for a credit card.
Side note: none of this is an argument against AI-written code, which I use daily and gladly. It is an observation that the AI collapsed the price of exactly one option out of three, and one day we'll act surprised when the costs of choosing that option every time come due.
Why machines never learned to buy
Economists call the frictions around a transaction its transaction costs, and there is nearly a century of literature on the idea; the plain version is that buying has always required being a person. Sitting through the sales call. Trying to decide if the sales materials actually mean that the product will serve your explicit need. Creating the account. Entering the card number, agreeing to the terms, expensing the invoice. For a software agent, every one of those steps is a wall, which means that for the entire history of automation, the effective price of "buy" to a machine has been infinite. We never noticed, because until recently machines couldn't build either. Then we handed them the ability to build and forgot to hand them the ability to do anything else.
That asymmetry is now being corrected, and quietly, by people mostly thinking about shopping rather than science. The web's HTTP 402 status code, "Payment Required," sat reserved and unused for some thirty years; there is now a protocol, x402, that uses it to let software pay for a resource in the middle of a request. Stripe and OpenAI have each published an open standard for agent-initiated purchases. I hold no strong opinion about which of these standards wins, and the details will take years to shake out. But the direction seems unmistakable: machine wallets, spending under budgets and constraints that a human defines, are becoming ordinary plumbing.
What changes when software can spend
The moment an agent can pay, the build-vs-buy decision stops being a reflex and becomes what it always should have been: arithmetic. And arithmetic is the one thing the agent is genuinely superb at.
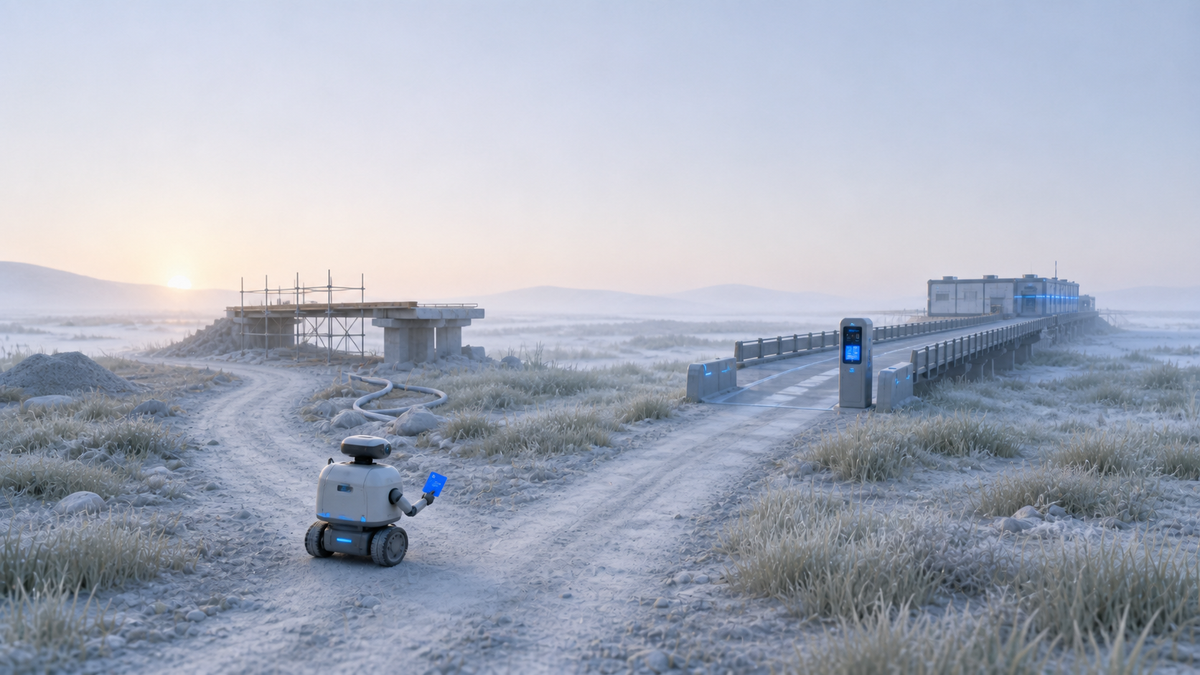
The agent finally has a purchasing card. Picture the scientist's agent a few years from now. It reads the folder, sizes the job, and then does something few assistants do today: it shops. It prices all three of its options honestly, its own inference, its own construction, and, for the first time, the purpose-built services that publish machine-readable prices, and it compares them the only way that matters, ownership against ownership. It knows what its pipeline will owe every time a format drifts. It knows it cannot manufacture provenance for its own conduct. So it spends a few dollars from a wallet that its human capped, keeps the clever one-off analysis for itself, and gets on with the science. The human is consulted about the question and the budget, not about the plumbing.
Two things about that future strike me as underappreciated. The first is that the agent will make this decision with a discipline almost no human brings to it. It has no ego invested in building, no sunk cost, no fondness for its own code, and no patience for a sales dinner. It will be the first buyer in history that actually prices total cost of ownership before committing, every single time, in seconds. Sellers of software should sit with that for a minute: your next customer may evaluate you the way a compiler evaluates syntax, and no amount of brand warmth will move it.
The second is that the deciding weight on the scale will often be the thing that seems most human: proof. An agent can generate code, but it cannot generate a trustworthy history of its own conduct; provenance has to be kept by something with no incentive to flatter the result. Durable records, versioned rules, an accountable chain from raw reading to published number: these are exactly what the skeptical reader demands and exactly what a pile of generated scripts cannot provide. In the machine-to-machine economy that I am describing, verifiability becomes a first-class good, something agents pay for deliberately because their humans require it. I find it quietly delightful that the most futuristic actor in this story will spend its money on the oldest scientific virtue we have... evidence.
I run a data platform company, so I have an obvious interest in a future where agents buy data infrastructure. Discount my enthusiasm accordingly. We are re-plumbing our own product on the assumption that some of our future customers will read JSON rather than webpages.
What stays human
I understand the instinct to find this future unsettling, machines spending money and choosing vendors without us. My honest reaction is closer to relief. Humans, myself included, were never good at build-vs-buy. We chose build because it was all we knew, or buy because the salesperson was likable, and we systematically ignored the invoices that arrive after month six. Moving that decision to an agent that can see all the costs at once does not remove human judgment; it relocates it to the places it belonged all along. Someone still decides which questions are worth asking. Someone still sets the budget and the bar for proof. Someone still stands up in the meeting where the number is challenged and says: here is how we know.
The scientist with the folder full of CSVs did not go into science to write parsing scripts, and the fact that we ever made that the price of admission was a compromise, not a principle. What wasn't possible then simply became status quo now, and everyone kind of "forgot" the compromise was made. The machines are about to un-forget it for us. Our job is to be ready with better questions, because for the first time in my career, the answers are about to get cheap.